Keras in Python, Rebuilding My 2020 Notebook (Step by Step)
Keras is a Python library for building neural networks, and since TensorFlow 2.16 it installs with TensorFlow. Using Keras in Python comes down to a few calls. You stack layers with keras.Sequential, pick a loss with compile, train with fit, score the result with evaluate, and save the whole model to one .keras file.
In eight steps, I build one that predicts the median house value of California districts from eight numbers, like income and house age. On districts it never saw, it misses by $35,351 on average. Plain linear regression on the same split misses by $53,330.
I first wrote a model like this in November 2020. I was teaching myself machine learning on the side, following Pierian Data’s TensorFlow 2.0 course, and I saved my notes as a notebook in this GitHub repo. I used it as a reference for some of my projects after that.
The repo is called Keras-Model-Predicting-House-Prices. The notebook inside predicts the price of a gem, from fake data that came with the course. This time the houses are real.
Every code block below runs top to bottom on Python 3.13.8, TensorFlow 2.21.0, Keras 3.15.1 and scikit-learn 1.9.1, and the output shown is what it printed. I ran it three times, once in a brand new virtual environment, and got the same numbers every time. Your last digits may differ on other hardware.
What is Keras, and how do Keras and TensorFlow fit together?
Keras is a high-level library, which means you describe the network in a few lines and Keras takes care of the details. A neural network is a stack of layers that turns input numbers into a prediction. It learns by nudging its internal numbers, called weights, a little after every batch of examples.
If that’s new to you, my introduction to neural networks covers the theory first.
Keras doesn’t do the heavy math itself. It hands that job to a backend, and Keras 3 can run on JAX, TensorFlow or PyTorch. The Keras getting started guide shows how to switch with the KERAS_BACKEND environment variable. With nothing set, my install used TensorFlow.
Here’s the part that trips people up when they search for TensorFlow and Keras. Older code imports it as from tensorflow.keras import ..., also called tf.keras. Since TensorFlow 2.16, installing TensorFlow installs Keras 3 as well.
And tf.keras now points at that same Keras 3. In my install, tf.keras reported version 3.15.1, the same as import keras. So the code below just writes import keras. If you want to see the TensorFlow layer underneath, my post on creating tensors in TensorFlow starts there.
What do you need before you start?
You need three things.
- Python 3.10 to 3.13. TensorFlow 2.21 only ships packages for those versions.
- A terminal. I ran every command on a Mac.
- Basic Python. I explain the machine learning parts as they come up.
TensorFlow’s install page lists Python 3.9 to 3.12 near the top and then says 2.21 supports 3.10 to 3.13 further down. Trust the second one. It’s the one that matches what pip can actually download.
You don’t need a GPU. The whole script, training included, finished in under 30 seconds on my Mac’s CPU.
The eight steps at a glance
Steps 1 to 4 get the data ready. Steps 5 to 8 build, train, test and save the model.
- Install Keras in Python in a virtual environment.
- Load the California housing data and spot its price ceiling.
- Split the data three ways for training, validation and testing.
- Normalize the features with a Keras layer.
- Build the model with
keras.Sequential. - Compile and train it with early stopping.
- Test it against linear regression.
- Predict and save the model.
Step 1. Install Keras in Python
Installing Keras in Python takes one pip command, but make a virtual environment first. That’s a private folder of packages for one project, so nothing here clashes with the rest of your Python setup.
python3.13 -m venv .venv
source .venv/bin/activate
pip install tensorflow scikit-learn pandas
pip install tensorflow pulls in Keras 3 for you. scikit-learn brings the dataset and the linear regression baseline, and pandas holds the table.
Step 2. Load the California housing data
We’re predicting the median house value of California districts, using scikit-learn’s California Housing dataset. It comes from the 1990 U.S. census, with one row per census block group, a small area that typically holds 600 to 3,000 people. The scikit-learn docs call these districts, so I will too.
Each row has eight inputs, called features. They are median income, median house age, average rooms and bedrooms per household, population, average household size, and the district’s latitude and longitude.
The target, the number we want to predict, is the district’s median house value in hundreds of thousands of dollars. So 2.07 means $207,000, in 1990 prices.
import keras
import numpy as np
from sklearn.datasets import fetch_california_housing
from sklearn.linear_model import LinearRegression
from sklearn.metrics import mean_absolute_error, r2_score
from sklearn.model_selection import train_test_split

keras.utils.set_random_seed(42)

housing = fetch_california_housing(as_frame=True)
X = housing.data
y = housing.target

print(X.shape)
print(list(X.columns))
print(y.describe().round(2))
(20640, 8)
['MedInc', 'HouseAge', 'AveRooms', 'AveBedrms', 'Population', 'AveOccup', 'Latitude', 'Longitude']
count 20640.00
mean 2.07
std 1.15
min 0.15
25% 1.20
50% 1.80
75% 2.65
max 5.00
Name: MedHouseVal, dtype: float64set_random_seed(42) fixes the random parts, like the starting weights, so you get the same model every run. as_frame=True gives you pandas tables instead of bare arrays. If pandas is new to you, my pandas tutorial for beginners covers the basics.
That’s 20,640 districts and 8 features. The median district is worth 1.80, or $180,000.
Why do 965 districts share one price?
Look at the max in that output. It prints as 5.00, which hides something.
capped = (y == y.max()).sum()
print(f"top value {y.max()}, districts at the top {capped}")
print(y.value_counts().head(3))
top value 5.00001, districts at the top 965
MedHouseVal
5.00001 965
1.37500 122
1.62500 117
Name: count, dtype: int64965 districts share the exact same top value, 5.00001, or $500,001. The next most common value shows up only 122 times. That’s not 965 neighborhoods landing on the same price by luck. It looks like a ceiling on the data, and it comes back in Step 7.
Step 3. Split the data three ways
A model needs three piles of data. The training set is what it learns from. The validation set is a practice exam it takes after every pass, and the test set is the final exam it sees once, at the very end.
X_train, X_test, y_train, y_test = train_test_split(X, y, test_size=0.2, random_state=42)
X_train, X_val, y_train, y_val = train_test_split(X_train, y_train, test_size=0.25, random_state=42)

X_train, X_val, X_test = X_train.to_numpy(), X_val.to_numpy(), X_test.to_numpy()
y_train, y_val, y_test = y_train.to_numpy(), y_val.to_numpy(), y_test.to_numpy()
print(len(X_train), len(X_val), len(X_test))
12384 4128 4128The first train_test_split holds back 20% for the test set. The second takes 25% of what’s left for validation, which is 20% of the whole. That leaves 60% for training. It’s the same split my KNN tutorial uses, with one extra cut for validation.
The last two lines turn the pandas tables into NumPy arrays. Keras works with arrays, and Step 4 doesn’t accept a DataFrame at all. Pass one to adapt and you get a TypeError about strings.
Step 4. Normalize the features with a Keras layer
The features sit on wildly different scales. Population runs into the thousands, while bedrooms per household hovers around 1. Neural networks usually train more smoothly when every input is on a similar scale.
So we normalize them. Normalizing shifts and scales each column so it averages 0 with a standard deviation of 1. Keras has a layer for that.
norm = keras.layers.Normalization()
norm.adapt(X_train)

for name, mean in zip(housing.feature_names, norm.mean.numpy()[0]):
    print(f"{name:10} {mean:8.2f}")
MedInc 3.87
HouseAge 28.59
AveRooms 5.41
AveBedrms 1.09
Population 1427.29
AveOccup 3.03
Latitude 35.64
Longitude -119.58adapt measures the mean and variance of each column. It only ever sees the training set. If it peeked at the test set, the final exam would leak into the studying, which is called data leakage.
My 2020 notes had the right comment on this exact line, “We only run it on the training set. To prevent data leakage from test set.” Past me got that part right.
Why a layer, and not scikit-learn’s scaler? Because the layer becomes part of the model. The Normalization docs say adapt stores the mean and variance as the layer’s weights. So when you save the model, the scaling goes with it, and you can feed it raw numbers later.
Step 5. Build the model
Building a model with Keras in Python means listing its layers in order.
model = keras.Sequential([
    keras.Input(shape=(8,)),
    norm,
    keras.layers.Dense(64, activation="relu"),
    keras.layers.Dense(64, activation="relu"),
    keras.layers.Dense(1),
])
model.summary()
Model: "sequential"
┏━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━┳━━━━━━━━━━━━━━━━━━━━━━━━┳━━━━━━━━━━━━━━━┓
┃ Layer (type) ┃ Output Shape ┃ Param # ┃
┡━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━╇━━━━━━━━━━━━━━━━━━━━━━━━╇━━━━━━━━━━━━━━━┩
│ normalization (Normalization) │ (None, 8) │ 17 │
├─────────────────────────────────┼────────────────────────┼───────────────┤
│ dense (Dense) │ (None, 64) │ 576 │
├─────────────────────────────────┼────────────────────────┼───────────────┤
│ dense_1 (Dense) │ (None, 64) │ 4,160 │
├─────────────────────────────────┼────────────────────────┼───────────────┤
│ dense_2 (Dense) │ (None, 1) │ 65 │
└─────────────────────────────────┴────────────────────────┴───────────────┘
Total params: 4,818 (18.82 KB)
Trainable params: 4,801 (18.75 KB)
Non-trainable params: 17 (72.00 B)Here’s what each line does.
keras.Input(shape=(8,))says every example has 8 numbers.normis the Normalization layer from Step 4, now the first thing every input passes through.Dense(64, activation="relu")is a layer of 64 neurons. Dense means each neuron connects to every value from the layer before.reluis the activation function. It passes positive numbers through and turns negatives into zero. That bend is what lets the network learn curves instead of only straight lines.Dense(1)is the output, one neuron for one predicted value. It has no activation, so the output isn’t bent or clipped. That’s the usual setup for predicting a number.
The summary counts the parameters. The first Dense layer has 576 because each of its 64 neurons gets a weight for each of the 8 inputs, plus one bias, so 8 times 64 plus 64.
The 17 non-trainable ones belong to the Normalization layer, 8 means, 8 variances and a count. Training never changes them.
I picked 64 neurons. It’s a common starting size, and it’s small enough to train in seconds on a CPU.
Step 6. Compile and train it
Training a Keras model takes two calls. compile sets how the model learns, and fit runs the learning on your training data.
model.compile(optimizer="adam", loss="mse", metrics=["mae"])optimizer="adam"is the algorithm that adjusts the weights after each batch. Adam is a common default.loss="mse"is mean squared error, the average of the squared misses. Training tries to make this number small.metrics=["mae"]adds mean absolute error, the average miss in the target’s own units. It’s easier to read than MSE, since 0.35 here means $35,000.
Then fit does the training.
early_stop = keras.callbacks.EarlyStopping(
    monitor="val_mae", patience=10, restore_best_weights=True
)
history = model.fit(
    X_train, y_train,
    validation_data=(X_val, y_val),
    epochs=200,
    batch_size=32,
    callbacks=[early_stop],
    verbose=0,
)
print("epochs run", len(history.history["loss"]))
print("best epoch", early_stop.best_epoch + 1)
epochs run 79
best epoch 69An epoch is one full pass over the training data. With batch_size=32, the model updates its weights after every 32 districts.
EarlyStopping checks the validation MAE after every epoch. If it doesn’t improve for 10 epochs in a row, which is what patience=10 means, training stops. restore_best_weights=True then puts back the weights from the best epoch, as the EarlyStopping docs describe.
I allowed up to 200 epochs. Training stopped at 79, and the best epoch was 69. best_epoch counts from zero, hence the + 1.
Rendered with Python from the run's output.
The dashed training line keeps sinking slowly. The solid validation line flattens out and wobbles. That gap is the start of overfitting, where a model memorizes its training data instead of learning patterns that carry over. My overfitting vs underfitting post goes deeper on that gap.
My 2020 notebook had none of this. It trained for a fixed 250 epochs with no validation set and hoped for the best.
Step 7. Test it against linear regression
Now the final exam. evaluate scores the model on the 4,128 test districts it has never seen.
test_mse, test_mae = model.evaluate(X_test, y_test, verbose=0)
print(f"test MAE {test_mae:.3f}, about ${test_mae * 100_000:,.0f}")
test MAE 0.354, about $35,351evaluate returns the loss and then each metric, in the order you compiled them. The average miss on districts the model never saw is $35,351.
Does the neural network beat linear regression?
Yes, on this data, and by a lot. On the same 4,128 test districts, the network’s average miss was $35,351 and linear regression’s was $53,330.
A number like $35,351 means little on its own, which is why the baseline matters. I trained scikit-learn’s LinearRegression on the same training set and scored both models on the same test set.
nn_pred = model.predict(X_test, verbose=0).ravel()

linear = LinearRegression().fit(X_train, y_train)
lin_pred = linear.predict(X_test)

for name, pred in [("linear regression", lin_pred), ("neural network", nn_pred)]:
    mae = mean_absolute_error(y_test, pred)
    print(f"{name:18} MAE ${mae * 100_000:,.0f}  R2 {r2_score(y_test, pred):.3f}")
linear regression MAE $53,330 R2 0.571
neural network MAE $35,351 R2 0.792| Model | Average miss (MAE) | R-squared |
|---|---|---|
| Linear regression | $53,330 | 0.571 |
| Keras neural network | $35,351 | 0.792 |
That’s about $18,000 less per district, and the network explains about 79% of the spread in prices against 57% for the straight line.
R-squared is the share of the spread in house values a model explains, where 1.0 would be perfect. I walk through it in my linear regression in Python post.
One difference in setup is worth saying. Both models learned from the same 12,384 districts, but the network also used the validation set to decide when to stop.
Why the gap? A straight line gives each feature one fixed effect everywhere. The network’s ReLU layers can bend, so income and location can matter differently in different places.
That’s the point of a baseline. It turns “is the neural network worth it?” into two numbers you can compare.
Rendered with Python from the run's output.
The squares are districts at the $500,001 top value. 13 of the 300 sampled districts sit there, and the network guessed lower for 12 of them. Whatever those districts are really worth, the data only says $500,001.
Step 8. Predict and save the model
Call model.predict on new rows to get predictions, and model.save to write the whole model to one .keras file. keras.models.load_model brings it back.
There’s no single house in this data. Each row is a district, so a prediction is a district’s median value. Here’s the first district in the test set.
district = X_test[:1]
print(dict(zip(housing.feature_names, district[0].round(2).tolist())))

pred = model.predict(district, verbose=0)[0, 0]
print(f"predicted ${pred * 100_000:,.0f}, actual ${y_test[0] * 100_000:,.0f}")
{'MedInc': 1.68, 'HouseAge': 25.0, 'AveRooms': 4.19, 'AveBedrms': 1.02, 'Population': 1392.0, 'AveOccup': 3.88, 'Latitude': 36.06, 'Longitude': -119.01}
predicted $46,242, actual $47,700The model says $46,242, and the real median was $47,700. X_test[:1] keeps the 2D shape, one row of eight columns, which is what predict expects.
Notice there’s no scaling step. The raw numbers go straight in, because the Normalization layer is inside the model.
Saving takes one line, and loading takes one more.
model.save("house_prices.keras")

loaded = keras.models.load_model("house_prices.keras")
print(f"loaded model predicts ${loaded.predict(district, verbose=0)[0, 0] * 100_000:,.0f}")
loaded model predicts $46,242The Keras saving guide describes a .keras file as a zip archive that holds the model’s configuration and its weights. The loaded copy predicts the same $46,242, scaling included.
What changed since my 2020 notebook?
The short version is that the scaling moved inside the model, a validation set now decides when to stop, the save format is .keras, and the data is real.
| 2020 notebook | This post | |
|---|---|---|
| Data | 1,000 rows of fake gem prices from the course | 20,640 California districts from the 1990 census |
| Import | tensorflow.keras | keras |
| Scaling | MinMaxScaler, outside the model | Normalization layer, inside the model |
| Model | 3 hidden layers of 4 ReLU neurons, rmsprop | 2 hidden layers of 64 ReLU neurons, adam |
| Training length | Fixed 250 epochs | Early stopping, stopped at 79 (best 69) |
| Validation set | None | 20% of the data |
| Save format | .h5, with a legacy warning | .keras |
| Loads in Keras 3.15.1 | Only with compile=False | Yes |
Here’s the 2020 repo as it stands today. The README credits the course and says the data isn’t real.
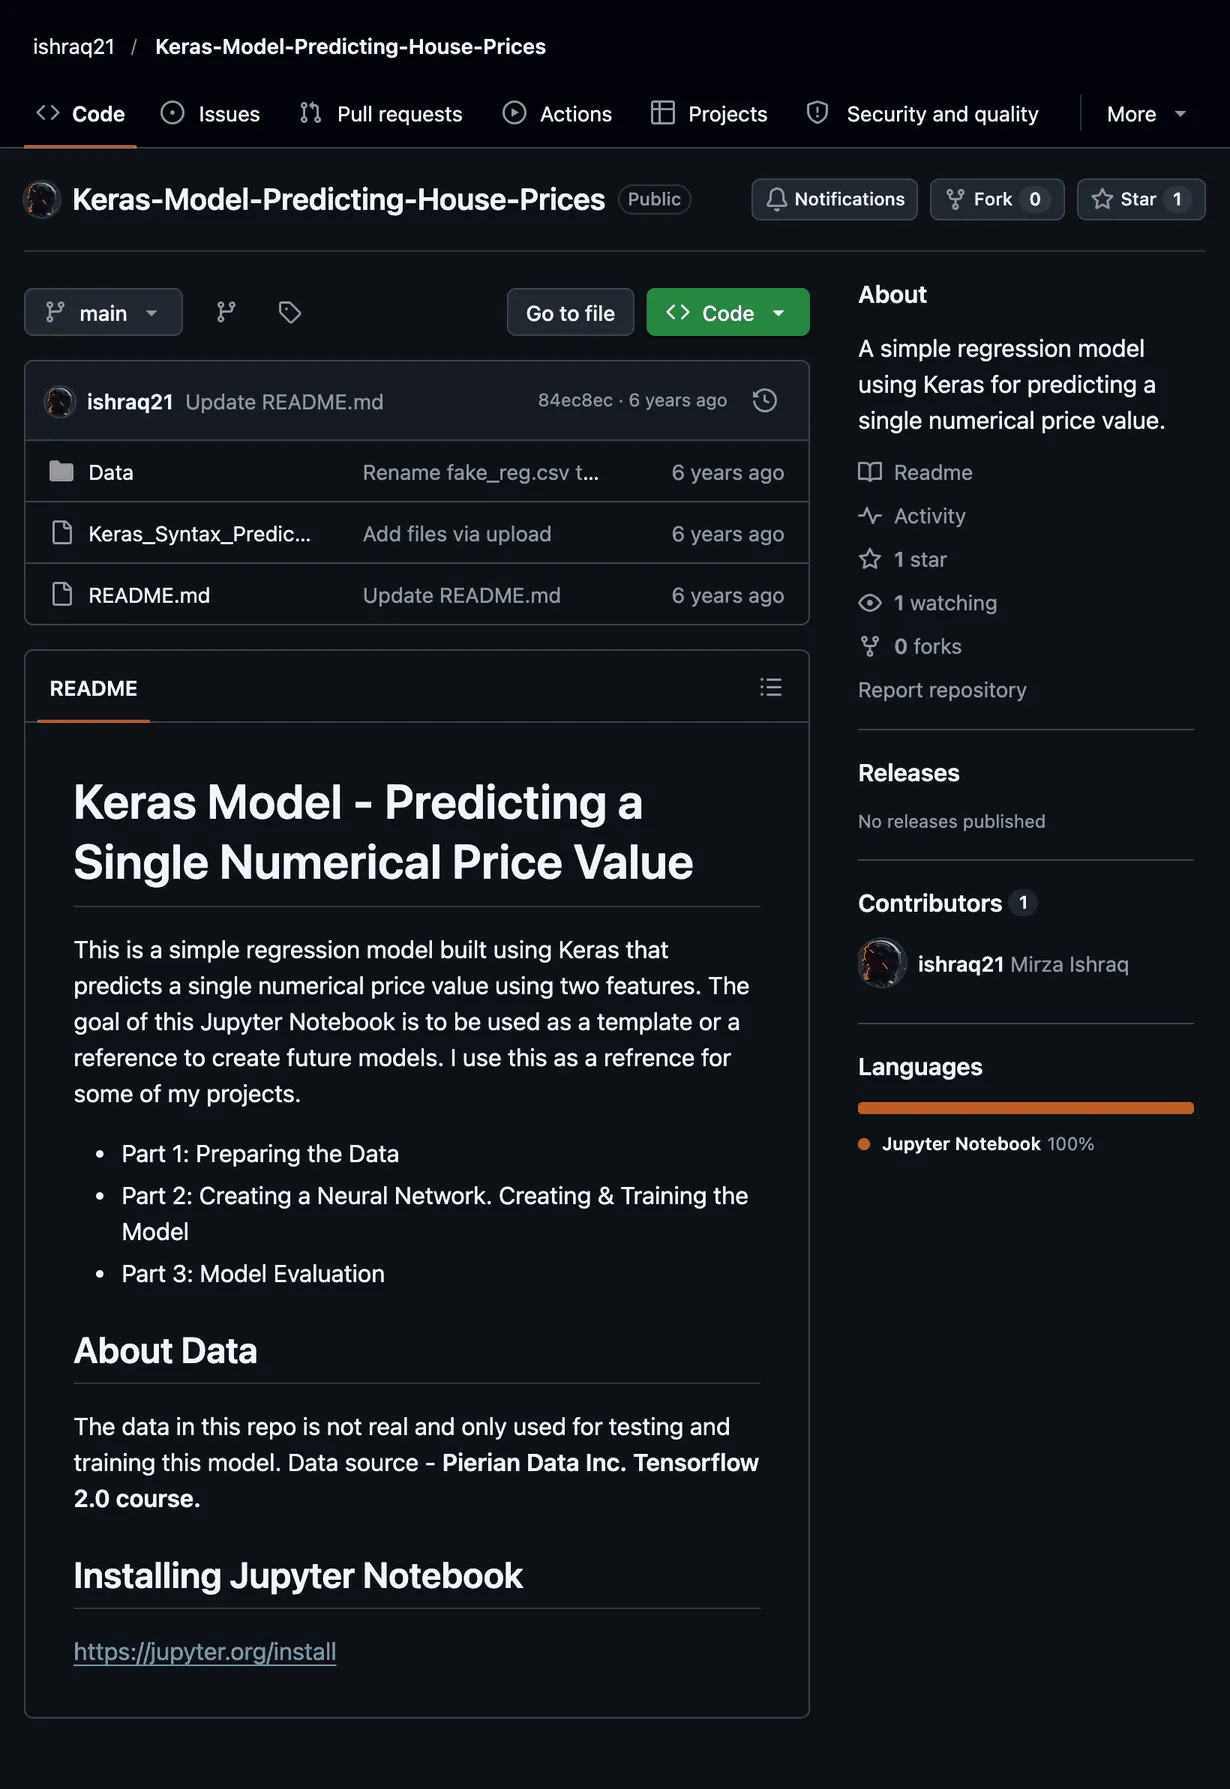
I reran the 2020 notebook on the same versions as this post. It failed on the first line that reads data. The notebook opens fake_reg.csv, but the repo stores the file as Data/fakeData.csv.
The commit history shows how that happened. I uploaded the CSV as fake_reg.csv in November 2020, then moved and renamed it a month later, on December 20. Nothing after that touched the notebook.
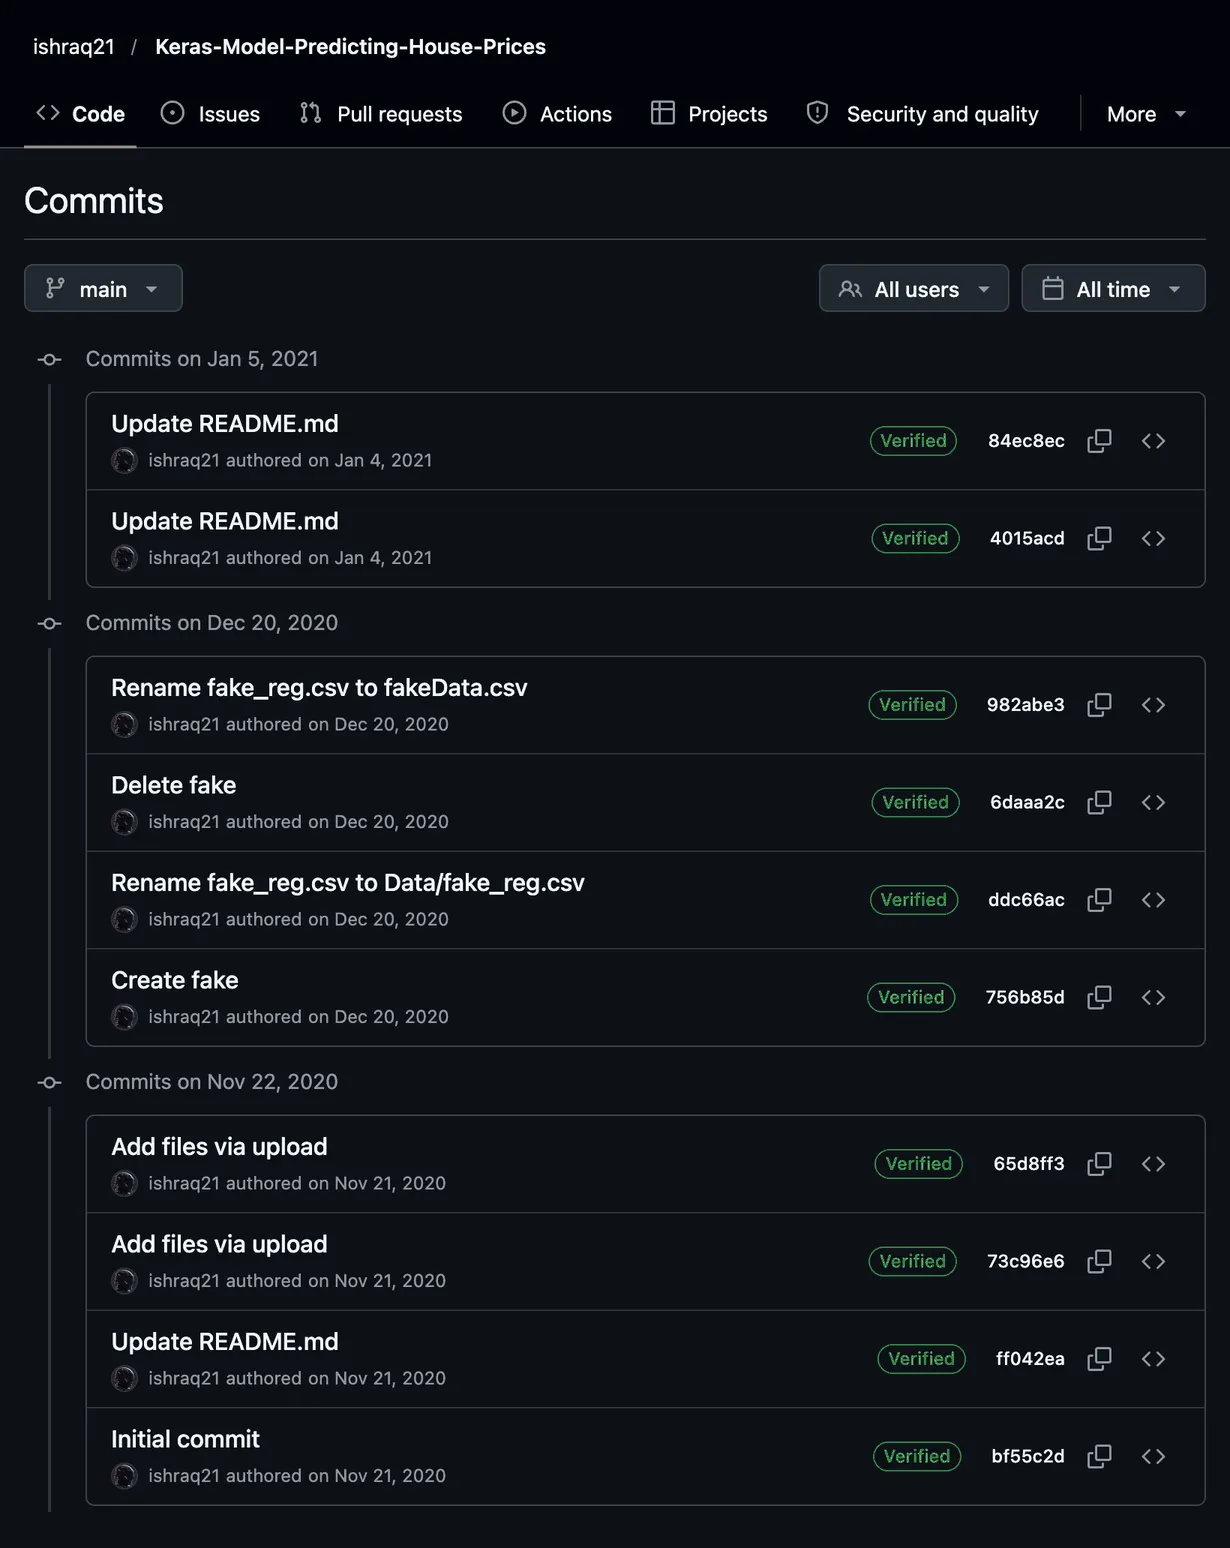
Both screenshots show my real public repo, captured on October 12, 2026.
So it doesn’t run from a fresh clone. After I copied the file to the expected name, the old from tensorflow.keras imports still worked, and the model trained.
Its model had three hidden layers of 4 ReLU neurons each, trained with the rmsprop optimizer for a fixed 250 epochs on data scaled by scikit-learn’s MinMaxScaler. Then it saved the model as myPriceModel.h5. Saving printed a warning that the HDF5 format “is considered legacy,” and loading it back failed with this error.
ValueError: Could not deserialize 'keras.metrics.mse' because it is not a KerasSaveable subclassPassing compile=False to load_model got the old file to load. If you have .h5 files lying around, that’s the first thing to try.
The bigger change is where the scaling lives. In 2020 the scaler sat outside the model, so every prediction needed a scaler.transform call first. Forget it, and the model quietly predicts from the wrong numbers.
That happened to me for real. My part of the BDA 594 group project in my Big Data Analytics master’s at SDSU, where we ranked NFL special teams players, reused this template almost line for line. Same layers, same 250 epochs, same .h5 save.
The copy also lost one line. It fit the scaler and scaled the test set, but it never ran X_train = scaler.transform(X_train). So that model trained on raw numbers and was tested on scaled ones. The notebook is in my grad projects repo.
With a Normalization layer inside the model, there is no separate step to forget.
What should you remember about Keras in Python?
pip install tensorflowinstalls Keras 3 as well. Writeimport keras, and use Python 3.10 to 3.13.- Split into training, validation and test sets before anything learns from the data.
- Put a Normalization layer inside the model and
adaptit on the training set only. - End a regression model with
Dense(1)and no activation. Compile withmseloss and trackmae. - Use
EarlyStoppingwithrestore_best_weights=Trueinstead of guessing the epoch count. - Train a linear regression baseline. Here the network cut the average miss from $53,330 to $35,351.
- Save to
.keras. An old.h5file may needcompile=Falseto load.
What’s the oldest notebook in your GitHub, and does it still run?